Failure-Latent Activation Risk Estimation in Robot Policies
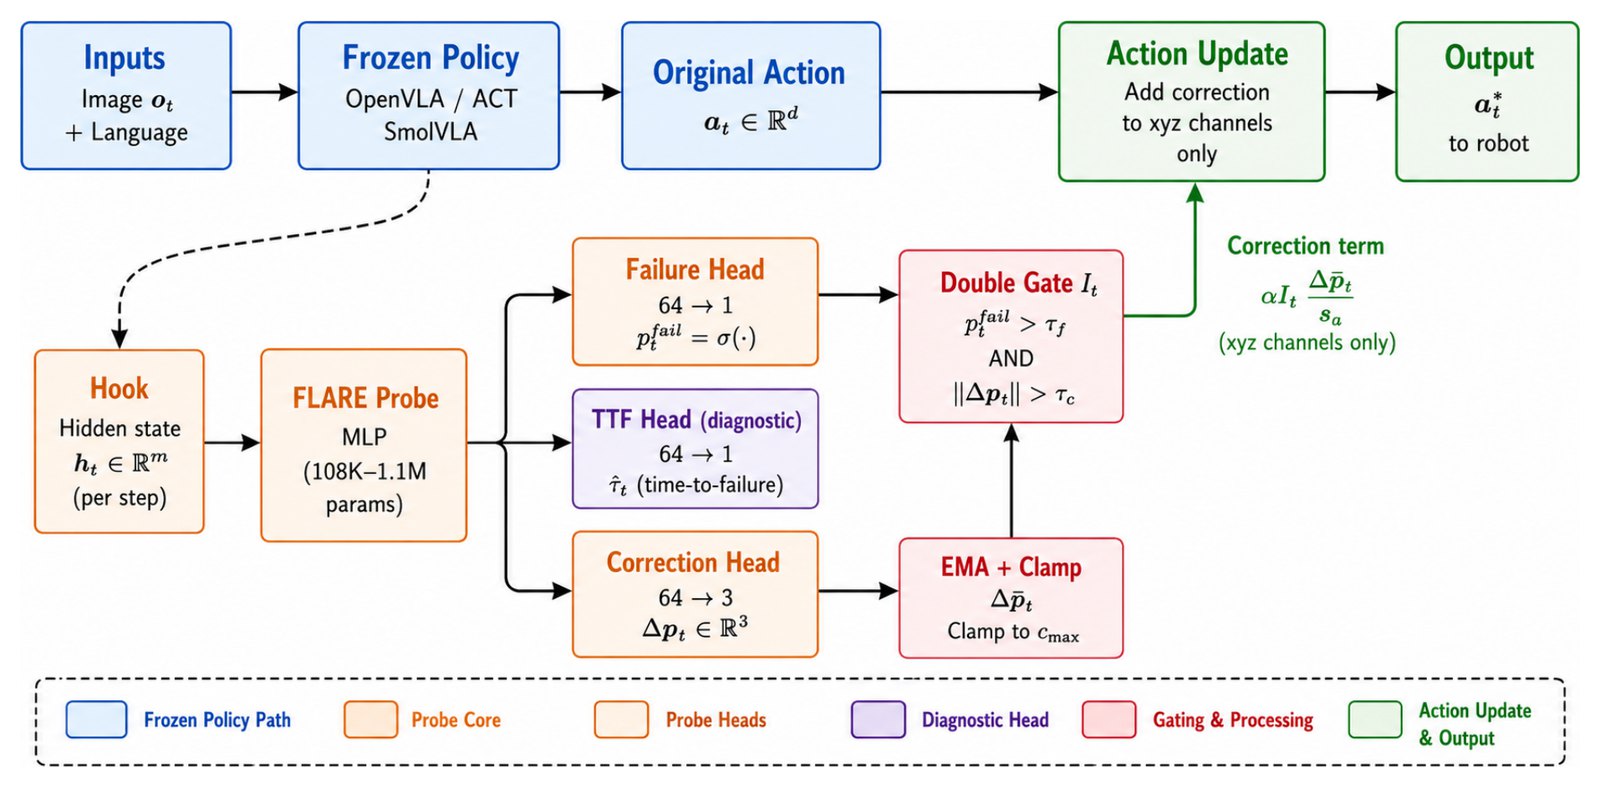
When a frozen robot policy is about to fail, does its hidden state already know? FLARE is a small probe that reads it and flags the failure in under a millisecond.
<1 msper step for the probe
0.889AUC on ACT in simulation, up 0.10 on a linear probe
0.73AUC on a real SO-101 arm, from 50 episodes
What it found
On LIBERO-Spatial, across 10,000 episodes, FLARE reaches AUC 0.832 on OpenVLA and 0.889 on ACT. One probe query per step was success-equivalent to searching 16 samples, at 6.1× lower latency.
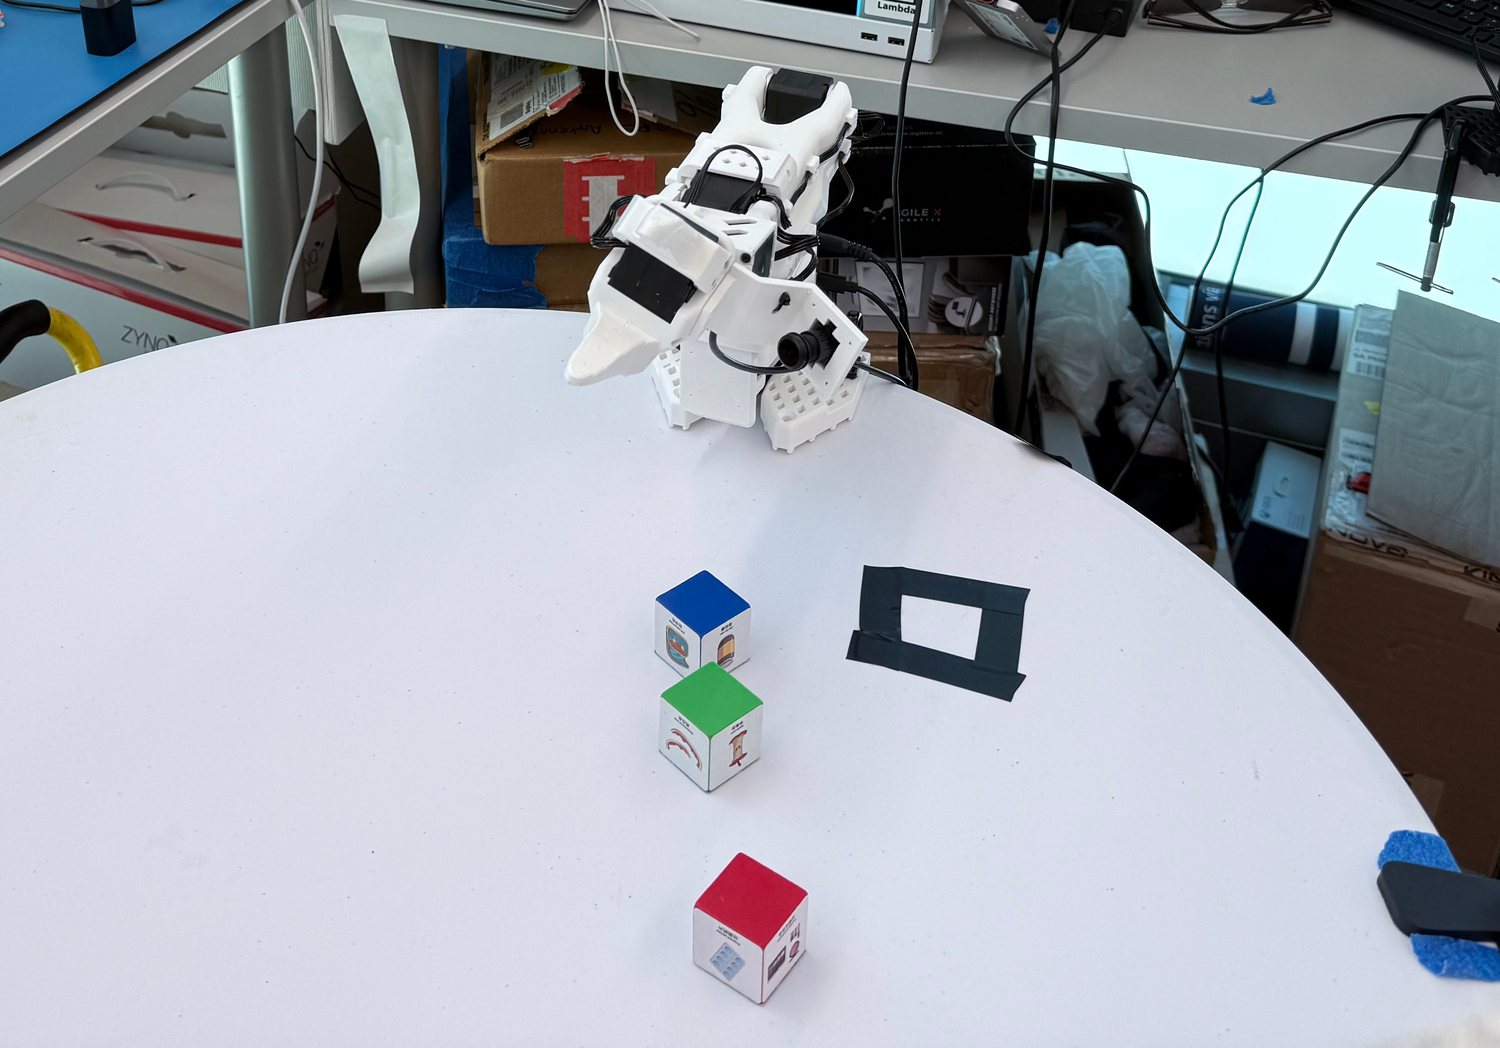
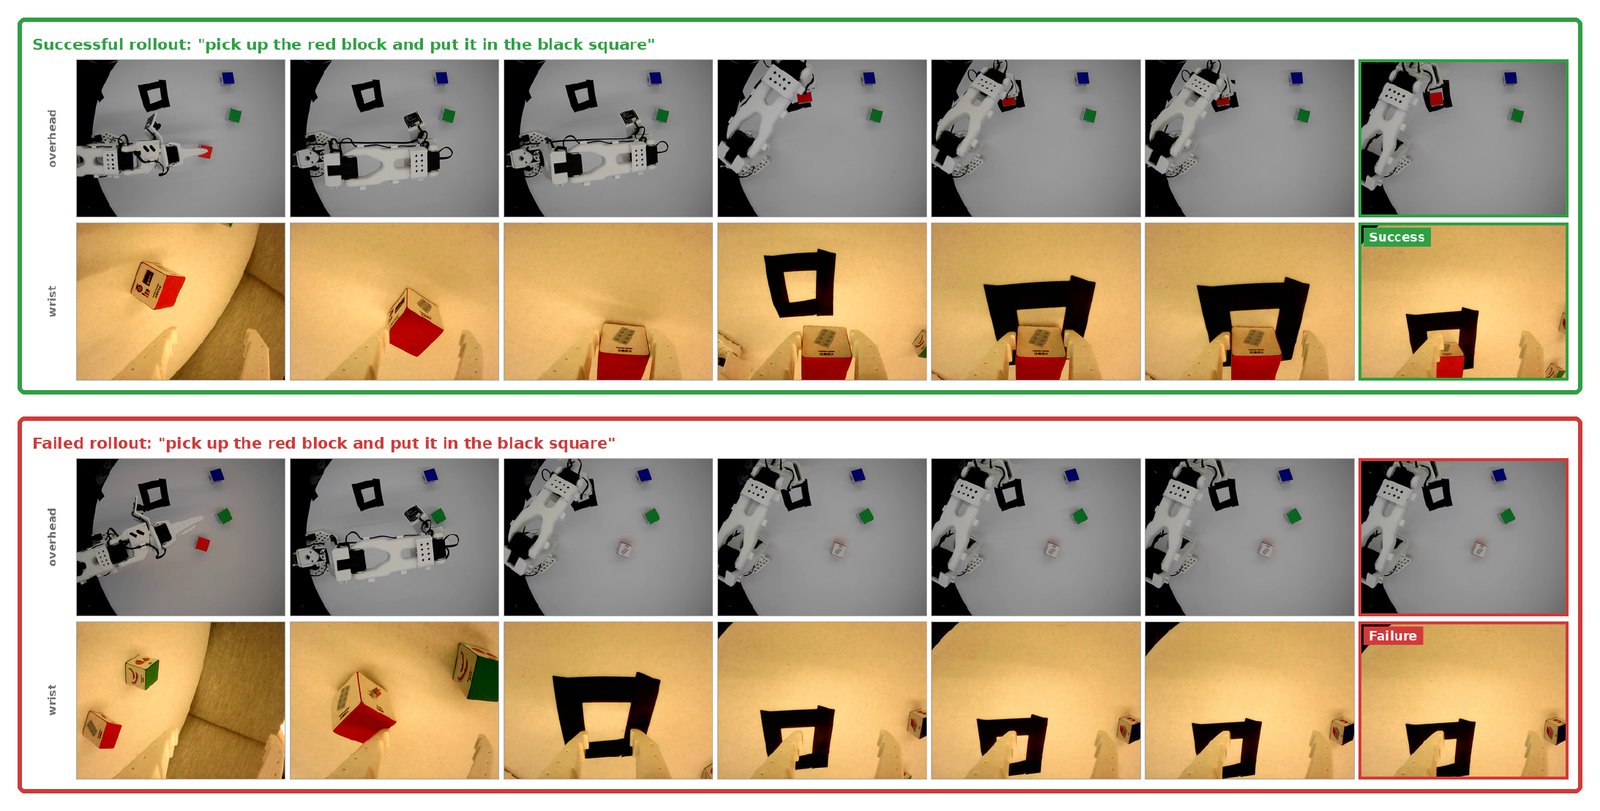
Ported to a real SO-101 arm, reusing the recipe but no weights, it anticipated failure at AUC 0.73 where a non-learned baseline fell to chance. The simulation-tuned threshold over-fired on hardware though, so deployment needs its own calibration.
The real SO-101 arm and the blocks on its table.The arm at its station.Success vs failure on a real SO-101 arm.
It was rejected
It was my first first-author paper, and it didn't get in. The reviews shaped how I test GAIN.